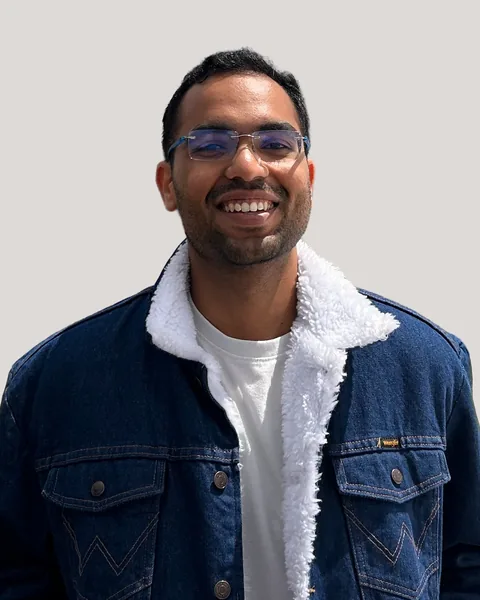
Hemant Kumawat
Applied Scientist, Gaming AI @ Microsoft · Seattle, WA
I’m an Applied Scientist on Microsoft’s Gaming AI team, building real-time vision-language models that understand gameplay. My research asks how agents can learn world models — compact enough to run in real time, rich enough to plan with, honest about what they can’t see — and how to turn multimodal foundation models into agents that act, in games and on robots. Ph.D. from Georgia Tech with Prof. Saibal Mukhopadhyay; internships at Qualcomm, Amazon Robotics and CMU.
🔬Research
Four open problems on the way to agents that model the world and act in it.
World models
🌍How do we learn world models an agent can plan with?
Generative models can imagine convincing futures, but planning needs models that respond to actions, stay consistent over long horizons and are cheap enough to run inside a control loop. I learn compact, action-conditioned dynamics — Koopman embeddings that let a linear controller act directly from pixels, and object-centric 3D occupancy world models — building toward controllable world models for games and robots.
Multimodal foundation models
🎮How do we turn foundation models that describe into agents that act?
Vision-language models can caption a frame, yet struggle to track state, ground language in action and stay truthful in real time. I work on closing that gap: real-time VLMs that understand gameplay at Microsoft and, in my Ph.D., decision transformers and Mamba policies that learn from interaction, and vision-action models adapted to new embodiments from little data.
Multi-agent world models
🕸️How should agents reason about what they can't see?
Real environments are partially observed: other agents are hidden, their interactions unknown, the future uncertain. I build stochastic generative models that infer hidden agents and their interactions from the ones we can see, spiking networks that learn interaction graphs from event streams, and forecasting for warehouse robot fleets — toward multi-agent world models that plan with uncertainty rather than around it.
Closed-loop perception
📡How can perception spend compute only where the task needs it?
Robots and on-device models can't afford to sense and process everything, everywhere. I build closed-loop perception in which the task decides what to look at: radar that steers a camera detector to the objects it misses (+14% recall, 3× less compute), LiDAR fired only where the camera points, and chirp-by-chirp radar with 3× lower latency — ideas that carry over to adaptive compute in foundation models.
📄Publications
15 papers · 161 citations · h-index 6 — Google Scholar, Oct 2026
MAPLE: Multimodal Mamba Agent for Event Based Policy with Adaptive Value Estimation
DFDNet: Directional Feature Diffusion for Efficient Fully-Sparse LiDAR Object Detection
Toward Efficient and Robust Sequential Chirp-Based Data-Driven Radar Processing for Object Detection
LUGA: Lightweight Uncertainty-Guided Sensing Resolution Adaptation for Energy Efficient Radar Processing
Adaptive Graph Structure Inference for Learning Multivariate Point Processes using Spiking Neural Networks
Intelligent Sensing-to-Action for Robust Autonomy at the Edge: Opportunities and Challenges
AdaCred: Adaptive Causal Decision Transformers with Feature Crediting
RoboKoop: Efficient Control Conditioned Representations from Visual Input in Robotics using Koopman Operator
STEMFold: Stochastic Temporal Manifold for Multi-Agent Interactions in the Presence of Hidden Agents
ChirpNet: Noise-Resilient Sequential Chirp Based Radar Processing for Object Detection
Cognitive Sensing for Energy-Efficient Edge Intelligence
STAGE Net: Spatio-Temporal Attention-based Graph Encoding for Learning Multi-Agent Interactions in the Presence of Hidden Agents
Radar Guided Dynamic Visual Attention for Resource-Efficient RGB Object Detection
A Methodology for Understanding the Origins of False Negatives in DNN Based Object Detectors
Task-Driven RGB-Lidar Fusion for Object Tracking in Resource-Efficient Autonomous System
| Name | Venue | Year | Topics | Role | Cites |
|---|---|---|---|---|---|
| 📄MAPLE: Multimodal Mamba Agent for Event Based Policy with Adaptive Value Estimation | RA-L | 2026 | Robot learning | First author | 0 |
| 📄DFDNet: Directional Feature Diffusion for Efficient Fully-Sparse LiDAR Object Detection | Preprint | 2025 | Perception | Co-author | 0 |
| 📄Toward Efficient and Robust Sequential Chirp-Based Data-Driven Radar Processing for Object Detection | T-RS | 2025 | Perception | Co-author | 1 |
| 📄LUGA: Lightweight Uncertainty-Guided Sensing Resolution Adaptation for Energy Efficient Radar Processing | SENSORS | 2025 | PerceptionEdge AI | Co-author | 1 |
| 📄Adaptive Graph Structure Inference for Learning Multivariate Point Processes using Spiking Neural Networks | IJCNN | 2025 | Multi-agent | Co-author | 0 |
| 📄Intelligent Sensing-to-Action for Robust Autonomy at the Edge: Opportunities and Challenges | DATE | 2025 | Edge AI | Co-author | 21 |
| 📄AdaCred: Adaptive Causal Decision Transformers with Feature Crediting | AAMAS | 2025 | Robot learning | First author | 14 |
| 📄RoboKoop: Efficient Control Conditioned Representations from Visual Input in Robotics using Koopman Operator | CoRL | 2024 | Robot learningWorld models | First author | 12 |
| 📄STEMFold: Stochastic Temporal Manifold for Multi-Agent Interactions in the Presence of Hidden Agents | L4DC | 2024 | Multi-agentWorld models | First author | 7 |
| 📄ChirpNet: Noise-Resilient Sequential Chirp Based Radar Processing for Object Detection | IMS | 2024 | PerceptionEdge AI | Co-first | 5 |
| 📄Cognitive Sensing for Energy-Efficient Edge Intelligence | DATE | 2024 | Edge AI | Co-author | 2 |
| 📄STAGE Net: Spatio-Temporal Attention-based Graph Encoding for Learning Multi-Agent Interactions in the Presence of Hidden Agents | Preprint | 2023 | Multi-agentWorld models | First author | 4 |
| 📄Radar Guided Dynamic Visual Attention for Resource-Efficient RGB Object Detection | IJCNN | 2022 | Perception | First author | 18 |
| 📄A Methodology for Understanding the Origins of False Negatives in DNN Based Object Detectors | IJCNN | 2022 | Perception | Co-author | 5 |
| 📄Task-Driven RGB-Lidar Fusion for Object Tracking in Resource-Efficient Autonomous System | T-IV | 2022 | Perception | Co-author | 71 |
No results. Try another filter.
MAPLE: Multimodal Mamba Agent for Event Based Policy with Adaptive Value Estimation
Cite
@article{kumawat2026maple,
  title   = {{MAPLE: Multimodal Mamba Agent for Event Based Policy with Adaptive Value Estimation}},
  author  = {Kumawat, Hemant and Mukhopadhyay, Saibal},
  journal = {IEEE Robotics and Automation Letters},
  volume  = {11},
  number  = {7},
  pages   = {8415--8422},
  doi     = {10.1109/LRA.2026.3693942},
  year    = {2026}
}DFDNet: Directional Feature Diffusion for Efficient Fully-Sparse LiDAR Object Detection
Cite
@misc{zhang2025dfdnet,
  title  = {{DFDNet: Directional Feature Diffusion for Efficient Fully-Sparse LiDAR Object Detection}},
  author = {Zhang, Meilong and Kumawat, Hemant and Mukhopadhyay, Saibal},
  note   = {Under review},
  year   = {2025}
}Toward Efficient and Robust Sequential Chirp-Based Data-Driven Radar Processing for Object Detection
Cite
@article{sharma2025sequential,
  title   = {{Toward Efficient and Robust Sequential Chirp-Based Data-Driven Radar Processing for Object Detection}},
  author  = {Sharma, Sudarshan and Kumawat, Hemant and Sen, Anuvab and Park, Jinhyeok and Mukhopadhyay, Saibal},
  journal = {IEEE Transactions on Radar Systems},
  volume  = {3},
  pages   = {1435--1448},
  doi     = {10.1109/TRS.2025.3622514},
  year    = {2025}
}LUGA: Lightweight Uncertainty-Guided Sensing Resolution Adaptation for Energy Efficient Radar Processing
Cite
@inproceedings{sharma2025luga,
  title     = {{LUGA: Lightweight Uncertainty-Guided Sensing Resolution Adaptation for Energy Efficient Radar Processing}},
  author    = {Sharma, Sudarshan and Park, Jinhyeok and Kumawat, Hemant and Mukhopadhyay, Saibal},
  booktitle = {2025 IEEE SENSORS},
  pages     = {1--4},
  doi       = {10.1109/SENSORS59705.2025.11330285},
  year      = {2025}
}Adaptive Graph Structure Inference for Learning Multivariate Point Processes using Spiking Neural Networks
Abstract
Modeling and predicting temporal point processes (TPPs) is critical in domains such as neuroscience, epidemiology, finance, and social sciences. We introduce the Spiking Dynamic Graph Network (SDGN), a novel framework that leverages the temporal processing capabilities of spiking neural networks (SNNs) and spike-timing-dependent plasticity (STDP) to dynamically estimate underlying spatio-temporal functional graphs. Unlike existing methods that rely on predefined or static graph structures, SDGN adapts to any dataset by learning dynamic spatio-temporal dependencies directly from the event data, enhancing generalizability and robustness. While SDGN offers significant improvements over prior methods, we acknowledge its limitations in handling dense graphs and certain non-Gaussian dependencies, providing opportunities for future refinement. Our evaluations, conducted on both synthetic and real-world datasets including NYC Taxi, 911, Reddit, and Stack Overflow, demonstrate that SDGN achieves superior predictive accuracy while maintaining computational efficiency. Furthermore, we include ablation studies to highlight the contributions of its core components.
Cite
@inproceedings{chakraborty2025sdgn,
  title     = {{Adaptive Graph Structure Inference for Learning Multivariate Point Processes using Spiking Neural Networks}},
  author    = {Chakraborty, Biswadeep and Kumawat, Hemant and Kang, Beomseok and Mukhopadhyay, Saibal},
  booktitle = {2025 International Joint Conference on Neural Networks (IJCNN)},
  pages     = {1--8},
  doi       = {10.1109/IJCNN64981.2025.11227765},
  year      = {2025}
}Intelligent Sensing-to-Action for Robust Autonomy at the Edge: Opportunities and Challenges
Abstract
Autonomous edge computing in robotics, smart cities, and autonomous vehicles relies on the seamless integration of sensing, processing, and actuation for real-time decision-making in dynamic environments. At its core is the sensing-to-action loop, which iteratively aligns sensor inputs with computational models to drive adaptive control strategies. These loops can adapt to hyper-local conditions, enhancing resource efficiency and responsiveness, but also face challenges such as resource constraints, synchronization delays in multi-modal data fusion, and the risk of cascading errors in feedback loops. This article explores how proactive, context-aware sensing-to-action and action-to-sensing adaptations can enhance efficiency by dynamically adjusting sensing and computation based on task demands, such as sensing a very limited part of the environment and predicting the rest. By guiding sensing through control actions, action-to-sensing pathways can improve task relevance and resource use, but they also require robust monitoring to prevent cascading errors and maintain reliability. Multi-agent sensing-action loops further extend these capabilities through coordinated sensing and actions across distributed agents, optimizing resource use via collaboration. Additionally, neuromorphic computing, inspired by biological systems, provides an efficient framework for spike-based, event-driven processing that conserves energy, reduces latency, and supports hierarchical control — making it ideal for multi-agent optimization. This article highlights the importance of end-to-end co-design strategies that align algorithmic models with hardware and environmental dynamics and improve cross-layer interdependencies to improve throughput, precision, and adaptability for energy-efficient edge autonomy in complex environments.
Cite
@inproceedings{trivedi2025sensing,
  title     = {{Intelligent Sensing-to-Action for Robust Autonomy at the Edge: Opportunities and Challenges}},
  author    = {Trivedi, Amit Ranjan and Tayebati, Sina and Kumawat, Hemant and Darabi, Nastaran and Kumar, Divake and Kosta, Adarsh Kumar and Venkatesha, Yeshwanth and Jayasuriya, Dinithi and Jayasinghe, Nethmi and Panda, Priyadarshini and Mukhopadhyay, Saibal and Roy, Kaushik},
  booktitle = {2025 Design, Automation \& Test in Europe Conference \& Exhibition (DATE)},
  pages     = {1--10},
  doi       = {10.23919/DATE64628.2025.10993258},
  year      = {2025}
}AdaCred: Adaptive Causal Decision Transformers with Feature Crediting
Abstract
Reinforcement learning (RL) can be viewed as a sequence modeling challenge, where the goal is to predict future actions based on past state-action-reward sequences. Traditional methods often rely on long trajectory sequences to capture environmental dynamics in offline RL scenarios. However, this can lead to a tendency to overemphasize the memorization of long-term representations, which hinders the models' ability to prioritize trajectories and learned representations that are specifically relevant to the task at hand. In this study, we present AdaCred, a novel approach that conceptualizes trajectories as causal graphs derived from short-term action-reward-state sequences. Our model dynamically adapts its control policy by identifying and eliminating low-importance representations, focusing instead on those that are most pertinent to the downstream task. Experimental results show that policies based on AdaCred require shorter trajectory sequences and consistently outperform traditional methods in both offline reinforcement learning and imitation learning settings.
Cite
@inproceedings{kumawat2025adacred,
  title     = {{AdaCred: Adaptive Causal Decision Transformers with Feature Crediting}},
  author    = {Kumawat, Hemant and Mukhopadhyay, Saibal},
  booktitle = {Proceedings of the 24th International Conference on Autonomous Agents and Multiagent Systems (AAMAS)},
  pages     = {1244--1252},
  doi       = {10.65109/vfqt2008},
  year      = {2025}
}RoboKoop: Efficient Control Conditioned Representations from Visual Input in Robotics using Koopman Operator
Abstract
Developing agents that can perform complex control tasks from high-dimensional observations is a core ability of autonomous agents that requires underlying robust task control policies and adapting the underlying visual representations to the task. Most existing policies need a lot of training samples and treat this problem from the lens of two-stage learning with a controller learned on top of pre-trained vision models. We approach this problem from the lens of Koopman theory and learn visual representations from robotic agents conditioned on specific downstream tasks in the context of learning stabilizing control for the agent. We introduce a Contrastive Spectral Koopman Embedding network that allows us to learn efficient linearized visual representations from the agent's visual data in a high dimensional latent space and utilizes reinforcement learning to perform off-policy control on top of the extracted representations with a linear controller. Our method enhances stability and control in gradient dynamics over time, significantly outperforming existing approaches by improving efficiency and accuracy in learning task policies over extended horizons.
Cite
@inproceedings{kumawat2025robokoop,
  title     = {{RoboKoop: Efficient Control Conditioned Representations from Visual Input in Robotics using Koopman Operator}},
  author    = {Kumawat, Hemant and Chakraborty, Biswadeep and Mukhopadhyay, Saibal},
  booktitle = {Proceedings of The 8th Conference on Robot Learning},
  series    = {Proceedings of Machine Learning Research},
  volume    = {270},
  publisher = {PMLR},
  year      = {2025}
}STEMFold: Stochastic Temporal Manifold for Multi-Agent Interactions in the Presence of Hidden Agents
Abstract
Learning accurate, data-driven predictive models for multiple interacting agents following unknown dynamics is crucial in many real-world physical and social systems. In many scenarios, dynamics prediction must be performed under incomplete observations, i.e., only a subset of agents are known and observable from a larger topological system while the behaviors of the unobserved agents and their interactions with the observed agents are not known. When only incomplete observations of a dynamical system are available, so that some states remain hidden, it is generally not possible to learn a closed-form model in these variables using either analytic or data-driven techniques. In this work, we propose STEMFold, a spatiotemporal attention-based generative model, to learn a stochastic manifold to predict the underlying unmeasured dynamics of the multi-agent system from observations of only visible agents. Our analytical results motivate STEMFold design using a spatiotemporal graph with time anchors to effectively map the observations of visible agents to a stochastic manifold with no prior information about interaction graph topology. We empirically evaluated our method on two simulations and two real-world datasets, where it outperformed existing networks in predicting complex multiagent interactions, even with many unobserved agents.
Cite
@inproceedings{kumawat2024stemfold,
  title     = {{STEMFold: Stochastic Temporal Manifold for Multi-Agent Interactions in the Presence of Hidden Agents}},
  author    = {Kumawat, Hemant and Chakraborty, Biswadeep and Mukhopadhyay, Saibal},
  booktitle = {Proceedings of the 6th Annual Learning for Dynamics \& Control Conference},
  series    = {Proceedings of Machine Learning Research},
  volume    = {242},
  pages     = {1427--1439},
  publisher = {PMLR},
  year      = {2024}
}ChirpNet: Noise-Resilient Sequential Chirp Based Radar Processing for Object Detection
Abstract
Radar-based object detection (OD) requires extensive pre-processing and complex Machine Learning (ML) pipelines. Previous approaches have attempted to address these challenges by processing raw radar data frames directly from the ADC or through FFT-based post-processing. However, the input data requirements and model complexity continue to impose significant computational overhead on the edge system. In this work, we introduce ChirpNet, a noise-resilient and efficient radar processing ML architecture for object detection. Diverging from previous approaches, we directly handle raw ADC data from multiple antennas per chirp using a sequential model, resulting in a substantial 15× reduction in complexity and a 3× reduction in latency, while maintaining competitive OD performance. Furthermore, our proposed scheme is robust to input noise variations compared to prior works.
Cite
@inproceedings{sharma2024chirpnet,
  title     = {{ChirpNet: Noise-Resilient Sequential Chirp Based Radar Processing for Object Detection}},
  author    = {Sharma, Sudarshan and Kumawat, Hemant and Mukhopadhyay, Saibal},
  booktitle = {2024 IEEE/MTT-S International Microwave Symposium (IMS)},
  pages     = {102--105},
  doi       = {10.1109/IMS40175.2024.10600387},
  year      = {2024}
}Cognitive Sensing for Energy-Efficient Edge Intelligence
Abstract
Edge platforms in autonomous systems integrate multiple sensors to interpret their environment. The high-resolution and high-bandwidth pixel arrays of these sensors improve sensing quality but also generate a vast, and arguably unnecessary, volume of real-time data. This challenge, often referred to as the analog data deluge, hinders the deployment of high-quality sensors in resource-constrained environments. This paper discusses the concept of cognitive sensing, which learns to extract low-dimensional features directly from high-dimensional analog signals, thereby reducing both digitization power and generated data volume. First, we discuss design methods for analog-to-feature extraction (AFE) using mixed-signal compute-in-memory. We then present examples of cognitive sensing, incorporating signal processing or machine learning, for various sensing modalities including vision, Radar, and Infrared. Subsequently, we discuss the reliability challenges in cognitive sensing, taking into account hardware and algorithmic properties of AFE. The paper concludes with discussions on future research directions in this emerging field of cognitive sensors.
Cite
@inproceedings{lee2024cognitive,
  title     = {{Cognitive Sensing for Energy-Efficient Edge Intelligence}},
  author    = {Lee, Minah and Sharma, Sudarshan and Wang, Wei Chun and Kumawat, Hemant and Rahman, Nael Mizanur and Mukhopadhyay, Saibal},
  booktitle = {2024 Design, Automation \& Test in Europe Conference \& Exhibition (DATE)},
  pages     = {1--6},
  doi       = {10.23919/DATE58400.2024.10546823},
  year      = {2024}
}STAGE Net: Spatio-Temporal Attention-based Graph Encoding for Learning Multi-Agent Interactions in the Presence of Hidden Agents
Abstract
Accurate prediction of trajectories for multiple interacting agents following unknown dynamics is crucial in many real-world critical physical and social systems where a group of agents interact with each other, leading to intricate behavior patterns at both the individual and system levels. In many scenarios, trajectory predictions must be performed under partial observations i.e., only a subset of agents are known and observable. Consequently, we can only observe the trajectories of a subset of agents with a sampled interaction graph from a larger topological system while the behaviors of the unobserved agents and their interactions with the observed agents are not known. In this work, we propose STAGE Net, a sequential spatiotemporal attention-based generative model to learn system dynamics with multiple interacting agents where some agents are completely unobserved (hidden) all the time. Our network utilizes the spatiotemporal attention mechanism with neural inter-node messaging to capture high-level behavioral semantics of the multi-agent system. Our analytical results motivate STAGE Net design using spatiotemporal graph with time anchors to effectively model complex multi-agent interactions with unobserved agents and no prior information about interaction graph topology. We evaluate our method on multiagent simulations with spring and charged dynamics and a motion trajectory dataset. Empirical results illustrate that our method outperforms existing multiagent interaction modeling networks in predicting trajectories of complex multiagent interactions even when we have a large number of unobserved agents.
Cite
@misc{kumawat2023stage,
  title        = {{STAGE Net: Spatio-Temporal Attention-based Graph Encoding for Learning Multi-Agent Interactions in the Presence of Hidden Agents}},
  author       = {Kumawat, Hemant and Chakraborty, Biswadeep and Mukhopadhyay, Saibal},
  howpublished = {OpenReview},
  url          = {https://openreview.net/forum?id=tsj6rDzI0V},
  year         = {2023}
}Radar Guided Dynamic Visual Attention for Resource-Efficient RGB Object Detection
Abstract
An autonomous system's perception engine must provide an accurate understanding of the environment for it to make decisions. Deep learning based object detection networks experience degradation in the performance and robustness for small and far away objects due to a reduction in object's feature map as we move to higher layers of the network. In this work, we propose a novel radar-guided spatial attention for RGB images to improve the perception quality of autonomous vehicles operating in a dynamic environment. In particular, our method improves the perception of small and long range objects, which are often not detected by the object detectors in RGB mode. The proposed method consists of two RGB object detectors, namely the Primary detector and a lightweight Secondary detector. The primary detector takes a full RGB image and generates primary detections. Next, the radar proposal framework creates regions of interest (ROIs) for object proposals by projecting the radar point cloud onto the 2D RGB image. These ROIs are cropped and fed to the secondary detector to generate secondary detections which are then fused with the primary detections via non-maximum suppression. This method helps in recovering the small objects by preserving the object's spatial features through an increase in their receptive field. We evaluate our fusion method on the challenging nuScenes dataset and show that our fusion method with SSD-lite as primary and secondary detector improves the baseline primary YOLOv3 detector's recall by 14% while requiring three times fewer computational resources.
Cite
@inproceedings{kumawat2022radar,
  title     = {{Radar Guided Dynamic Visual Attention for Resource-Efficient RGB Object Detection}},
  author    = {Kumawat, Hemant and Mukhopadhyay, Saibal},
  booktitle = {2022 International Joint Conference on Neural Networks (IJCNN)},
  pages     = {1--8},
  doi       = {10.1109/IJCNN55064.2022.9892184},
  year      = {2022}
}A Methodology for Understanding the Origins of False Negatives in DNN Based Object Detectors
Abstract
In this paper we present two novel complementary methods namely the gradient analysis and the activation discrepancy analysis to analyze the perception failures occurring inside the DNN based object detectors. The gradient analysis localizes the nodes within the network that fail consistently in a scenario, thus creating a 'signature' of False Negatives (FNs). This method traces a set of False Negatives through the network and finds sections of the network that contribute to this set. The signatures show the location of the faulty nodes is sensitive to input conditions (such as darkness, glare etc.), network architecture, training hyperparameters, object class etc. Certain nodes of the network fail consistently throughout the training process thus implying that some False Negatives occur due to the global optimization nature of Stochastic Gradient Descent (SGD) based training. This analysis requires the knowledge of False Negatives and therefore can be used for post-hoc diagnostic analysis. On the other hand, the activation discrepancy analysis analyzes the discrepancy in forward activations of a DNN. This method can be conducted online and shows that the pattern of the activation discrepancy is sensitive to input conditions and detection recall.
Cite
@inproceedings{samal2022origins,
  title     = {{A Methodology for Understanding the Origins of False Negatives in DNN Based Object Detectors}},
  author    = {Samal, Kruttidipta and Kumawat, Hemant and Wolf, Marilyn and Mukhopadhyay, Saibal},
  booktitle = {2022 International Joint Conference on Neural Networks (IJCNN)},
  pages     = {1--8},
  doi       = {10.1109/IJCNN55064.2022.9892390},
  year      = {2022}
}Task-Driven RGB-Lidar Fusion for Object Tracking in Resource-Efficient Autonomous System
Abstract
Autonomous mobile systems such as vehicles or robots are equipped with multiple sensor modalities including Lidar, RGB, and Radar. The fusion of multi-modal information can enhance task accuracy but indiscriminate sensing and fusion in all modalities increase demand on available system resources. This paper presents a task-driven approach to input fusion that minimizes the utilization of resource-heavy sensors and demonstrates its application to Visual-Lidar fusion for object tracking and path planning. The proposed spatiotemporal sampling algorithm activates Lidar only at regions-of-interest identified by analyzing visual input and reduces the Lidar 'base frame rate' according to the kinematic state of the system. This significantly reduces Lidar usage, in terms of data sensed/transferred and potentially power consumed, without a severe reduction in performance compared to both a baseline decision-level fusion and state-of-the-art deep multi-modal fusion.
Cite
@article{samal2022task,
  title   = {{Task-Driven RGB-Lidar Fusion for Object Tracking in Resource-Efficient Autonomous System}},
  author  = {Samal, Kruttidipta and Kumawat, Hemant and Saha, Priyabrata and Wolf, Marilyn and Mukhopadhyay, Saibal},
  journal = {IEEE Transactions on Intelligent Vehicles},
  volume  = {7},
  number  = {1},
  pages   = {102--112},
  doi     = {10.1109/TIV.2021.3087664},
  year    = {2022}
}💼Experience
MS Applied Scientist, Gaming AI — Microsoft 2026 — now
- Built efficient, real-time game-understanding VLMs for adaptive, context-aware game assistance, and persistent player profiles that power experiences such as game recaps and recommendations.
- Designed evaluation pipelines for Microsoft Copilot that detect hallucinations and assess session and query quality, pinpointing failure points to accelerate targeted model and prompt improvements.
QC Research Intern — Qualcomm · ADAS Vision May — Aug 2025
Multi-modal, object-centric 3D occupancy world models · mentored by Amin Ansari
- Designed a query-centric semantic occupancy framework using sparse, trackable 3D Gaussian queries anchored to object-level primitives for efficient scene understanding.
- Proposed a Gaussian-to-voxel splatting strategy — 2× faster runtime and 30% lower memory than projection-based baselines (in submission).
GT Graduate Research Assistant — Georgia Tech · GREEN Lab Jan 2021 — Dec 2025
advised by Saibal Mukhopadhyay
- Efficient RL — sample-efficient multimodal RL with contrastive spectral Koopman encoding: 10× lower compute and +20% accuracy (CoRL 2024).
- Long-horizon sequence learning — adaptive causal decision transformers with separate local and long-horizon representations for offline RL (AAMAS 2025).
- Multi-agent dynamics — stochastic generative graph models with neural ODEs and spatiotemporal graph attention for partially observable systems (L4DC 2024).
- Closed-loop perception — noise-resilient RGB / LiDAR / radar processing that adapts memory and compute to real-time needs (IEEE T-IV, IJCNN, IMS).
- Vision-action adaptation — guiding a vision-action model’s generation toward a target domain for cross-embodiment and cross-task transfer with limited data.
AR Applied Scientist II Intern — Amazon Robotics May — Aug 2024
Multi-agent probabilistic behavior models for robots · mentored by Andreas Kolling
- Designed a goal-conditioned forecasting model to predict slowdowns and deadlocks of Proteus robots in dense warehouses.
- Built a scalable multi-agent interaction engine estimating inter-robot influence across 20 TB of real-world sensing and occupancy-grid data.
- Integrated goal-aware trajectory prediction with planning to reduce navigation conflicts — an order-of-magnitude improvement in coordination.
RI Research Scholar — Robotics Institute · Carnegie Mellon May — Aug 2019
Planning & control for evasive maneuvers in autonomous vehicles · mentored by John M. Dolan
- Combined iLQR with RRT* to plan evasive maneuvers with large tire slip — including drifting — and deployed the planner in ROS simulation and on an RC car avoiding suddenly-appearing obstacles at speed. (code)
IITB Student Project Lead, Self-Driving Car Team — SeDriCa · UMIC, IIT Bombay 2019 — 2020
- Led an interdisciplinary team of 50 students across three international robotics competitions.
- Managed an INR 4.5M budget and built a vendor & sponsorship network worth INR 3M with Velodyne, Ouster, Continental, Aptiv and NVIDIA.
🎓 Education
- Georgia Institute of Technology — M.S. & Ph.D., Electrical & Computer Engineering · 2021 — 2025 · Advisor — Prof. Saibal Mukhopadhyay
- Indian Institute of Technology Bombay — B.Tech, Mechanical Engineering & Computer Science · 2016 — 2020
📰News
🎤Service & talks
Reviewer
Talks
- Vision-Language Models 101
Cohere For AI · community talks with Vaishaal Shankar - Task-Driven Model Learning
Cohere For AI
Mentoring
- Georgia Tech SURE – Intel REU
2023 · ROS sensing & perception stack for the Unitree A1 quadruped - Ph.D. student mentor, Georgia Tech
2022 – 2025 · analog-to-feature object detection, event-camera activity recognition, CARLA closed-loop control - Autonomous Robotics Summer Program, IIT Bombay
2018 – 2019 · weekly lectures on localization, vision, planning & control for ~40 students
Get in touch. Happy to talk research, collaborations or ideas — email is fastest.
Last edited October 2026